
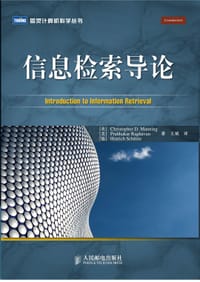
书籍介绍
这不是一本读起来令人愉悦的书。不少读者坦言其中章节“看不懂”,数学推导与算法细节对初学者并不友好;也有人遗憾“部分内容介绍得不够深入”。但正因如此,它反而成为一面镜子,照出信息检索这门学科的真实面貌:它不是零散技巧的堆砌,而是围绕“如何在海量数据中查找目标”这一核心问题,系统展开的严密体系。从倒排索引、布尔检索,到词项划分、数值计算,全书始终在回答同一个根本问题。适合那些不满足于“会用搜索引擎”,而想搞清其背后原理、并准备真正进入检索或数据挖掘方向的人。它或许不够轻松,但足够扎实。
作者简介
Christopher D. Manning,1989年毕业于澳大利亚国立大学,1995年获斯坦福大学语言学博士学位,曾先后在卡内基-梅隆大学、悉尼大学教授语言学,1999年起任斯坦福大学计算机科学和语言学副教授,其主要研究方向是统计自然语言处理、信息提取与表示,以及文本理解和文本挖掘等。
Prabhakar Raghavan,毕业于印度理工学院,后获加州大学伯克利分校计算机科学博士学位,自2005年起担任Yahoo!研究中心负责人,同时也是斯坦福大学计算机科学系顾问教授。其主要研究方向是文本及Web数据挖掘、组合优化、随机算法等,此前曾任Verity公司CTO,在IBM研究院担任过管理工作。
Hinrich Schütze,斯坦福大学博士,现任斯图加特大学自然语言处理研究所理论计算语言学主任。他在美国硅谷工作过多年,曾担任过Enkata公司首席科学家。
AI导读
核心看点
- 系统讲解搜索引擎核心技术,涵盖索引构建与检索
- 深入剖析倒排索引、文档聚类及向量空间模型原理
- 结合机器学习与数值计算,实现理论与实战结合
读者共识
- 作为入门教材体系完整,适合建立宏观知识框架
- 内容偏向传统检索理论,缺乏最新深度学习技术
- 部分章节描述不够深入,建议搭配其他书籍学习
精彩摘录
- "The term “unstructured data” refers to datawhich does not have clear, semantically overt, easy-for-a-computer structure."
- "A proximity operator is a way of specifying that two terms in a query must occur close to each other in a document, where closeness may be measured by limiting the allowed number of intervening words or by reference to a structural unit such as a sentence or paragraph."
- "INTERSECTWITHSKIPS(p1, p2) 1 answer ← h i 2 while p1 = NIL and p2 = NIL 3 do if docID(p1) = docID(p2) 4 then ADD(answer, docID(p1)) 5 p1 ← next(p1) 6 p2 ← next(p2) 7 else if docID(p1) < docID(p2) 8 then if hasSkip(p1) and (docID(skip(p1)) ≤ docID(p2)) 9 then while hasSkip(p1) and (docID(skip(p1)) ≤ "
- "(1) How many keys are we likely to have? (2) Is the number likely to remain static, or change a lot, and in the case of changes, are we likely to only have new keys inserted, or to also have some keys in the dictionary be deleted? (3) What are the relative frequencies with which various keys will be"
- "1. Retain the first letter of the term. 2. Change all occurrences of the following letters to ’0’ (zero): ’A’, E’, ’I’, ’O’, ’U’, ’H’, ’W’, ’Y’. 3. Change letters to digits as follows: B, F, P, V to 1. C, G, J, K, Q, S, X, Z to 2. D,T to 3. L to 4. M, N to 5. R to 6. 4. Repeatedly remove one out of e"
- "BSBINDEXCONSTRUCTION() 1 n ← 0 2 while (all documents have not been processed) 3 do n ← n +1 4 block ← PARSENEXTBLOCK() 5 BSBI-INVERT(block) 6 WRITEBLOCKTODISK(block, fn) 7 MERGEBLOCKS( f1, . . . , fn; fmerged)"
- "SPIMI-INVERT(token_stream) 1 output_ f ile = NEWFILE() 2 dictionary = NEWHASH() 3 while (free memory available) 4 do token ← next(token_stream) 5 if term(token) / ∈ dictionary 6 then postings_list = ADDTODICTIONARY(dictionary, term(token)) 7 else postings_list = GETPOSTINGSLIST(dictionary, term(toke"
- "VBENCODENUMBER(n) 1 bytes ← hi 2 while true 3 do PREPEND(bytes, n mod 128) 4 if n < 128 5 then BREAK 6 n ← n div 128 7 bytes[LENGTH(bytes)] += 128 8 return bytes VBENCODE(numbers) 1 bytestream ← hi 2 for each n ∈ numbers 3 do bytes ← VBENCODENUMBER(n) 4 bytestream ← EXTEND(bytestream, bytes) 5 retur"


下载
收藏