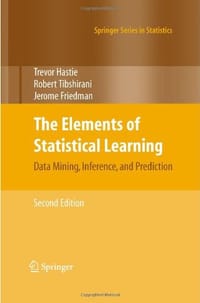
书籍介绍
这不是一本教你'用机器学习'的书,而是一本教你'理解机器学习为什么成立'的书。读者反复提到'相见恨晚''高屋建瓴''常读常新'——它适合在亲手写过代码、踩过坑、被算法迷惑之后回头细读,而非零基础入门。全书以统计决策理论为统一框架,把数据挖掘、机器学习、生物信息里彼此割裂的方法收拢到共同概念之下,重概念而轻公式堆砌。但'重概念'不等于'容易':多位读者直言它'不适合入门''会打击积极性''数学太深',并强调'光看书不行,必须把内容coding出来'。它真正适合的是愿意亲自推导算法、追问方法背后统计原理的人;读它会让你不再停留在调用库,而是看清每个算法为何有效、在何处失效。
作者简介
Trevor Hastie, Robert Tibshirani, and Jerome Friedman are professors of statistics at Stanford University. They are prominent researchers in this area: Hastie and Tibshirani developed generalized additive models and wrote a popular book of that title. Hastie co-developed much of the statistical modeling software and environment in R/S-PLUS and invented principal curves and surfaces. Tibshirani proposed the lasso and is co-author of the very successful An Introduction to the Bootstrap. Friedman is the co-inventor of many data-mining tools including CART, MARS, projection pursuit and gradient boosting.
AI导读
核心看点
- 统计视角统合机器学习核心概念
- 重概念阐释而非纯数学推导
- 涵盖监督学习与模型选择经典方法
读者共识
- 理论深度极高,入门门槛较高
- 常读常新,适合反复研读
- 经典巨著,值得投入时间精读
精彩摘录
- "LAR uses least squares directions in the active set of variables. Lasso uses least square directions; if a variable crosses zero, it is removed from the active set. Boosting uses non-negative least squares directions in the active set."
- "the bias of the 1-nearest-neighbor estimate is often low, but the variance is high."
- "Monte Carlo is an extremely bad method; it should be used only when all alternative methods are worse"
- "有一个关于Metropolis算法的故事,非常流行:一晚,Edward、Metropolis和Marshall在派对上讨论这个问题,在鸡尾酒餐巾纸上写出了这个闻名的算法。他们最终的论文之所以写上妻子的名字,是为了安抚被整晚的技术性讨论所烦扰的女人Arianna和Augusta"
- "Bagging; or Bootstrap AGGregatING, is an extension of bootstrapping to classification and regression problems. The main idea is to sample with replacement from the training data so that we now have B training data sets, each having n′≤n observations. The machine-learning algorithm is trained on each"
- "还是觉得对这本书相见恨晚,研一写那么都web app有毛用啊,就应该踏踏实实的多读书啊~ 还好去实习了,还好发现原来啥都不知道,还好坚持把这本书啃完了,虽然理解的较为粗陋,要不要去读个博呢......真苦恼~"
- "Both k-nearest neighbors and least squares end up approximating conditional expectatios by averages."
- "However, with a 0 − 1 outcome, this computation simplifies. We order the predictor classes according to the proportion falling in outcome class 1. Then we split this predictor as if it were an ordered predictor."
目录
Preface to the Second Edition
Preface to the First Edition
1 Introduction
2 Overview of Supervised Learning
2.1 Introduction
显示全部
用户评论
绝对不适合入门,很多东西都学了一遍再回来看才能更多理解作者在写什么。真的是高屋建瓴,常读常新。
没看完……稍微翻了一下
:无
好感动啊。
第二版已经第十次修订了,作者网站有免费的pdf下载,难度略大。。。
看了一半待补完中 先码 读得好辛苦哇
比花书还难啃,但涉及的内容非常全面,讲解也比较细致。不是天才的话,得沉下心细读,有很多地方一次两次根本看不懂,有时候得思考三五天
比想象的容易读,一节就讲一小件事,不过需要自己搜索才能理解的细节很多。
当时做助教,写习题课讲义是很好的参考书,另外补充了写搜到的havard、普林讲义
补标神书,每次翻出来看都有新体会,这种剖析入微鞭辟入里的归纳分析能力,有就是有,没有就是没有,默默流下羡慕的泪水……
挺简洁,适合有一定基础的人啃,但是如果不是专业做ML的就没必要看了...

Springer的其他书籍查看全部
 200 Years of Friedrich Engels
 Deepfakes
 Statistical Foundations, Reasoning and Inference: For Science and Data Science
 Introduction to Linear and Matrix Algebra
 Studien zur Struktur des Bewusstseins
 nternet of Things (IoT)
求书
收藏